Friday, March 27, 2015

UF Dashbuilder - Real time dashboards

   Dashboard solutions face different scenarios when it comes to data retrieval. While some dashboards do not require frequent updates as the data doesn't change very often or even rarely, other dashboards may require constant updates, because its data changes at a very fast pace. Therefore, we can classify our dashboards into two main groups:

  • Analitics: usually focused on the analysis of information about the past (historical/statistics), or about information that is known in advance (forecasts). The main trait of these dashboards is that data does not change very often and the time frame is usually long. Some examples: A company's sales evolution and forecast, sport statistics in general, etc.

  • Real time: their main trait is that data changes at a very fast pace. Therefore, this requires to update the indicators & reflect the changes in the UI frequently. Usually, the data is bound to a very short time frame, such as the last 10 seconds. Real time dashboards are typically used to monitor critical resources or systems, for example: Health display sensors, IT resources, air traffic control, etc. 

   Here is a comparison table which summarizes the main features of both:

    Analytics  Real-time  
 Data changes very often                                No Yes   
 Time frame    Any  Short   
 Amount of information    Any  Little   
 Dashboard updates  Rarely  Frequent   


  Dashbuilder is a general purpose dashboard solution. One of its design goals is to support both approaches. The following video shows an example of a real time dashboard built using the Dashbuilder GWT Client API (do not forget to select HD). The dashboard contains some metrics about an emulated cluster (the values shown are not real).


Real time dashboard example

   The dashboard is part of the Dashbuilder examples gallery and it's basically a GWT UI binder widget (source code here).

   Not only we allow for creating programmatic dashboards but also for custom ones created by end users. The next video (select HD) is a demo of how to create a real-time dashboard from scratch using the tooling. Here again, we're using the emulated cluster metrics data set, so the values shown are not real.

Creating a real-time dashboard

    As you can see, Dashbuilder covers a wide range of scenarios. As we introduced in this blog entry, data can be extracted from different systems. Once you have the data you can easily create your own visualizations. Both the analytics and real-time approaches are supported out of the box.


Friday, March 20, 2015

UF Dashbuilder - Metric visualizations

  A metric is a very useful type of visualization for displaying a single value for a given data property. For example:

  • The number of running processes in a server, memory used, CPU load, I/O throughput, etc...
  • The number of tweets received last week
  • The total travel expenses in a company
   The next screenshot shows a sample dashboard using the new metric visualization recently added to Dashbuilder. 


Sales dashboard example

   The entire dashboard is consuming the same data set, although every displayer has been configured with the proper settings. Next, we are going to see how those metrics indicators can be created using the tooling.

 Metric displayer

   As you can see below, a new "Metric" visualization type has been added to the Displayer Editor.

Displayer editor - Metric visualization type
Displayer editor - Metric visualization type 


   Once the "Metric" option has been selected, next step is to configure the data retrieval (see below, the "Data" tab). From this tab we need to:

  1. Select the source data set. In this case we have chosen the "Sales opportunities" example, which is a Java Bean generated data set containing the sales of a virtual company from the last 2 years until 3 years in the future.
  2. Select the metric to display. In this case we have selected the total sum of the opportunities closed within the current company's fiscal year. To do so, from the "Filters" section, we have added a filter on the property "closingDate". 


Metric displayer configuration

   After configuring the data retrieval, the last step is to adjust the "Display" settings. First of all, the metric needs a title. Secondly, the metric format can also be adjusted. There are 2 settings involved:

Expression

    It's a mathematical operation applied to the value retrieved from the data set. In our case, we are using "value/1000" as we want to display thousand dollars. Thousands are easier to understand by end users as sales amounts are usually big figures.
 
   We can combine the most common mathematical operators:
   
              *  => Multiply
              /   => Divide
              +  => Add
              -   => Subtract

   For example: 
  • "value*1.21"  => Amount plus 21% tax"
   Actually, we can use any valid JavaScript expression. For instance, "Math.sqrt(value)", square root, is also valid.

Pattern

   It's used to format the value obtained after applying the above expression. In our case we want to use the "$" currency symbol together with the "K" suffix as we want to indicate the value displayed is formatted in thousand dollars. f.i: "$ 10,345.23 K".  Pattern expressions are based on the default Java notation format for numbers. Some examples:

  • "#,###"            => "10,300"            no decimal part
  • "$#,###.##"     => "$10,300.45"     decimal part, currency symbol
  • "000000.000"  => "010300.453"    leading and trailing zeros, no commas


   That's all for today. As you can see, in Dashbuilder, has never been so easy to create & configure metrics visualizations on top of your data. Thanks for reading and stay tuned!


Tuesday, March 10, 2015

UF Dashbuilder - Activity monitoring in jBPM

   Last week, the jBPM team announced the 6.2.0.Final release (announcement here). In this release (like in previous ones) you can author processes, rules, data models, forms and all the assets of a BPM project. You can also create or clone existing projects from remote GIT repositories and group such repositories into different organizational units. Everything can be done from the jBPM authoring console (aka KIE Workbench), a unified UI built using the Uberfire framework & GWT.

   In this latest release, they have also added a new perspective to monitor the activity of the source GIT repositories and organizational units managed by the tooling (see screenshot below). The perspective itself it's just a dashboard displaying several indicators about the commit activity. From the dashboard controls it is possible to:

  • Show the overall activity on our repositories
  • Select a single organizational unit or repository
  • List the top contributors
  • Show only the activity for an specific time frame

  In this video you can see the dashboard in action (do not forget to select HD).

Contributors Perspective

  Organizational units can be managed from the menu Authoring>Administration>Organizational Units. Every time an organizational unit is added or removed the dashboard is updated.

Administration - Organizational Units 

   Likewise, from the Authoring>Administration>Repositories view we can create, clone or delete repositories. The dashboard will always feed from the list of repositories available.

Administration - Repositories


   As shown, activity monitoring in jBPM can be applied not only to the processes business domain but also to the authoring lifecycle in order the get a detailed view of the ongoing development activities.

How it's made


The following diagram shows the overall design of the dashboard architecture. Components in grey are platform components, blue ones are specific to the contributors dashboard.

Contributors dashboard architecture

  These are the steps the backend components take to build the contributors data set:

  • The ContributorsManager asks the platform services for the set of available org. units & repos. 
  • Once it has such information, it builds a data set containing the commit activity.
  • The contributors dataset is registered into the Dashbuilder's DataSetManager.

   All the steps above are executed on application start up time. Once running, the ContributorsManager also receives notifications form the platform services about any changes on the org. units & repositories registered, so that the contributors data set is synced up accordingly. 


   From the UI perspective, the jBPM's contributors dashboard is an example of a hard-coded dashboard built using the Dashbuilder Displayer API, which was introduced in this previous blog entry. The ContributorsDashboard component is just a GWT composite widget containing several Displayer instances feeding from the contributors data set.

   (The source code of the contributors perspective can be found here)


    This has been a good example of how to leverage the Dashbuilder technology to build activity monitoring dashboards. In the future, we plan for applying the technology in other areas within jBPM, like, for instance, an improved version of the jBPM process dashboard. We will keep you posted!

Thursday, March 5, 2015

Dashbuilder 6.2.0 released

The 6.2.0 Final release is available for download in the dashbuilder.org website.


  • Improved import/export support for unattended dashboard deployment. This allows for automating the movement of dashboards between different environments (dev/test/prod). Further details in the following 6.2.0 book's chapter. 
  • Added support for Weblogic 12c and Sybase DB (ASE 15.7) 

Tuesday, March 3, 2015

UF Dashbuilder - Rendering Subsystem

   More and more data is being collected nowadays, but collecting lots of data does not make any sense until these data can be extracted, analyzed and interpreted to make it understandable for business people. Data visualization is one of the key points of this process: data visualization is the presentation of data in a pictorial or graphical format. There exist several ways of displaying and representing these data such as tables or charts.

Data visualization software is wide extended in the market, there exist lots of libraries that provides the ability to create data tables and all kind of charts. Some of them are proprietary, some open source, some provides specific graphs and others are designed to be used in specific scenarios.

In Dashbuilder, we think the best approach is to be able to adapt to any of those libraries easily. It allows the developer to use all the power of the Dashbuilder's data set API and display the data as user expects, using different data visualization components from different libraries that can be adapted to every situation.

These visualization components that integrate the visualization libraries with Dashbuilder Data Set API are called Displayers. Dashbuilder provides by default some displayer components, such as the Google bar, pie and table displayers, or the Lienzo bar chart displayer, among others.

Another concept that comes into play is the Renderer Library:  a Dashbuilder component that allows the framework to use any third party data visualization library. It allows the communication between data set API and the way how data is visualized. The goal of a renderer is to provide a Displayer for each of the visualizations supported.

As you can see, data visualization is the last stage in business data analysis; as it's what the end user will see and use to take business decisions. So it's very important to talk about how Dashbuilder renders the data and how it adapts to any situation by integrating and handling third party data visualization libraries.

This article explains the internals of the Dashbuilder rendering subsystem, its architecture and the design of the different components and interfaces involved.


The rendering subsystem

   The rendering subsystem in Dashbuilder is the responsible for generating the different kinds of visualization components, such as bar charts, pie charts, area charts, bubble charts, tables, maps and so on.

These are some examples of visualization components provided by default:

GWT Bar and Pie Charts


The main advantage of the rendering subsystem is that it's not tied to any visualization library, as it provides a pluggable mechanism in order to use your favorite one.

Data visualization libraries are pluggable. What does that mean?


   Dashbuilder is a data visualization framework that provides the ability to query, collect and organize your business data, but its goal is not focused in developing and providing data visualization components on the client side; it just provides the grouped, filtered an sorted data to use in those visualization components, that can be provided by any third party data visualization library.

Summarizing, the rendering subsystem provides a pluggable mechanism that connects the data set API with a data visualization component, and it allows to use any third party library to visualize it. 

This external data visualization mechanism is represented by the  RendererLibrary interface and managed by the RendererLibLocator as you can see in the following diagram: 

Renderer subsystem main interfaces

As an example, consider the following two charts. Both display the same chart type and same data but using different data visualization libraries: GWT and Lienzo:

Bar Chart - Lienzo vs GWT


Renderer Library

   A RendererLibrary is a component that displays the data using an specific visualization library. Its main goal is to provide a data Displayer component for each visualization component the visualization library provides.

For example, consider the GWT charting library. As it provides a bar chart, the Dashbulder's Google Renderer library will provide the GoogleBarChartDisplayer. As it provides a pie chart, the Dashbulder's Google Renderer library will provide the PieBarChartDisplayer. And make it extensible for all kind of GWT charts.

The following UML diagram shows an example of a RendererLibrary implementation for Google GWT charting.

In this example, the renderer implementation class is GoogleRenderer (implements Renderer interface) and it provides a GoogleDisplayer based class (implements Displayer interface). Note that GoogleDisplayer class extends some other abstract Google base classes, but it's up to the developer the architecture for it. Dashbuilder just requires to implmenent the Displayer interface for drawing the component.

Google Renderer & Displayer classes diagram

As you can see in the diagram above, each RendererLibrary has a unique identifier. But as most important, a RendererLibrary component must provide two methods: draw and redraw, which are used by the framework as: draw method to init & render the visualization for the first time, and redraw to get and display the latest data changes.

It's important to note that each third party data visualization library can provide custom functionality and custom settings for a visualization component that are not present in the same component from another library.

For those interested in developing a new renderer, please just take a look at the current implementations of the  GoogleRenderer and LienzoRenderer in GitHub.

Available rendering libraries

   Dashbuilder supports by default:
  • GWT - Data visualization library that provides several chart types that are build using the popular GWT framework. Provided by Google.

    The project is located at Google Code and you can find the gallery here.
  • Lienzo  - Data visualization library that  it's still a prototype under development and not ready to be used in production environments. It provides, at this stage, two chart types: bar & pie. It's tight integrated with Dashbuilder and will provide extended functionality. Keep updated on it!

    Note that it's Open Source and distributed by Ahomé Innovation Technologies.

    The project is located at GitHub and you can find the gallery here.
      
These are the visualization components supported by each Rendering Library:

Renderer LibraryBar ChartPie ChartArea ChartLine ChartBubble ChartMeter ChartTableMap
GWTXXXXXXXX
Lienzo XX------

IMPORTANT: In future releases we will integrate new renderer libraries in order to support other visualization frameworks such as D3. Stay tuned!


The rendering process

   Once your are familiarized with the basic components in Dashbuilder, let's explain how the rendering process works. Rendering is the process of generating a component or an image from a given model by a computer program. In Dashbuilder, the rendering process allows for getting & draw a Displayer instance from a given DisplayerSettings configuration.

In the previous article, we talked about Displayers and how to create them. Now we are going to give some insights about the internals, and how Dashbuilder uses the renderer libraries to create & draw a  Displayer.

The rendering process implies:
  • To perform a data set look up
Given a data set (looked up from an external system) the users want to display the data in a certain way, by performing operations on it, such as grouping, filtering or sorting. This is the initial step to achieve data visualization: collect and organize your business data in a concrete way that will allow the business decision maker to analyze and interpret it. (In this previous article you can get all the details about the data set lookup process).
  • To provide the settings for the data visualization component that will display the information
At this point, the data is already collected and organized, next step is to decide which data visualization library to use and configure it for your purposes.
  • To obtain a Displayer component from Renderer class
Once data set is collected, organized and the user have decided & configured the data visualization library to use, next step is to obtain the Displayer component that matches all these requirements. This displayer is provided by the renderer class.
  • To draw the data visualization component (draw the Displayer instance)
Having the Displayer component instance it's time to show the data visualization component to the end user. To achieve that goal the Displayer component provides two methods: draw and redraw.

Rendering process in action

Next lines gets you into a deep detail in Dashbuilder architecture and how component interact to achieve the rendering process.

Consider your are creating a view (MyView) with a bar chart component using Dashbuilder. Your view source code would be similar to:

Example of view that uses a Bar Chart Displayer

The following diagram shows the sequence of calls between all the components involved during this bar chart displayer creation:


Displayer lookup sequence diagram
  1.  Build the settings for your Displayer component that will be used to show the bar chart.
     
    1. Build the displayerSettings instance from the factory methods that provide DisplayerSettingsFactory
       
    2. The settings instance contains the data set look up, the renderer library to use, the data visualization component to render and its settings
        
  2. Build a DisplayerHelper instance and use it to show the component (see init method)
     
    1. Obtain the Displayer component instance for your settings.
        
      1. Use the helper class DisplayerHelper to perform a displayer look up by using the method lookupDisplayer.  As you can see, to look up a displayer you have to provide the settings as method argument.
          
      2. DisplayerHelper delegates the look up of the displayer to the DisplayerLocator class and uses the returned instance to apply other configurations.
          
      3. The DisplayerLocator uses the RendererLibLocator component to locate the data visualization component specified by the settings instance. It's done by calling the method lookupRenderer. The result is a RendererLibrary instance, that is the responsible to provide a Displayer component that will display the data by using the settings provided.
          
    2. Use Displayer component API methods to draw the data visualization component.
        
      1. Once we have a Displayer component instance that matches our settings, it's time to draw the data visualization component, in this case, the bar chart.
          
      2. The DisplayerHelper class provides a method for showing the data visualization component: draw. This method takes the Displayer instance as argument and perform all the operation to draw the chart.
          
      3. Note that DisplayerHelper delegates the draw logic to the RendererLib instance, as it's each renderer library the responsible to draw the data in a certain way and using a certain library.

Conclusion


Data visualization is one of the most important aspects in any data analysis software, it provides an understandable way to analyze your business data.

In Dashbuilder we don't want to force end users to see and analyze all kind of data in the same way, we don't want to be tied or focused to an specific data visualization component, as depending on the nature of the data, a different visualization technique or library could be required.

For those reasons we think the best approach is to provide a rendering subsystem that can be integrated with any third party data visualization library, as it provides an extensible and scalable way to analyze and display your business data!

UF Dashbuilder Displayer Editor & API

  In the previous article, we introduced the data set API and how to perform data set look ups. Next step is to visualize this data set in a graphical way. So translating that into Dashbuilder language: to create a Displayer. A Displayer is a component responsible for rendering a data visualization component such as a bar chart, pie chart, tables, etc. This article explains how you can create a displayer to visualize your data. 

There exist two methods:


  • The Data Displayer UI Editor

    This is a UI component used to configure all the data set look up, displayer settings and other stuff. Can be used to create, update or remove data displayers at runtime.
  • The Dashbuilder's Displayer API

    Instead of creating the displayer at runtime using the UI, you can create displayers at compile time using the Dashbuilder's API.   


Creating a displayer from the UI

You can create, update or remove displayers at runtime using the Displayer Editor. This is the initial screen of this component:


Data Displayer Editor component

As you can see, there exist three main tabs:
  • Types tab - Allows to select the displayer type, such as bar chart, pie chart, table, etc.
      
  • Data tab - Allows to configure the data set look up for that displayer in order to fetch the data that will be displayed.
      
  • Display tab - Allows to select a renderer and configure the settings for the displayer type selected. the set of settings available varies depending on the displayer type and renderer selected.
So the steps to create or update a displayer are:


  • Choose the desired visualization type from the type tab. In this example. a Line Chart is selected.


Data Displayer Editor - Type tab


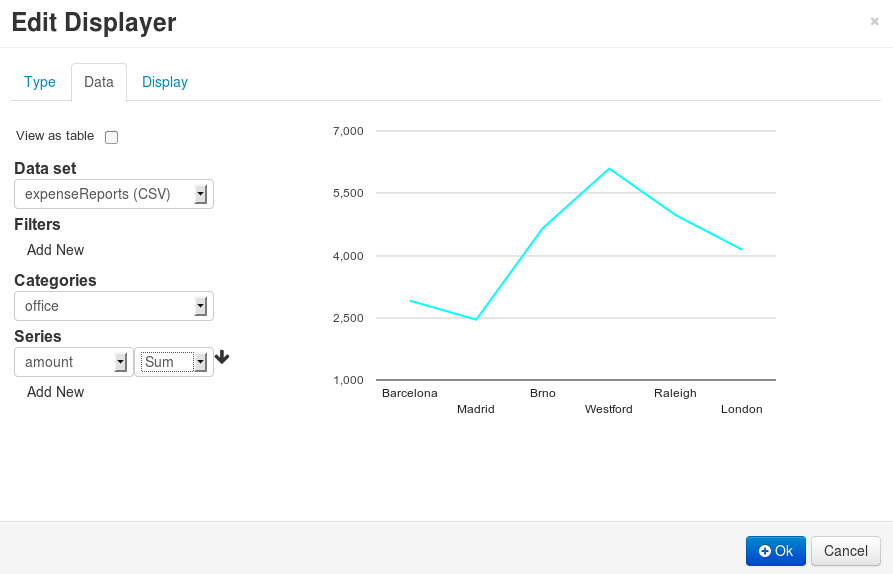
  • Click on the Data tab and configure the data lookup settings.


Data Displayer Editor - Data tab
    • First step is to select a Data Set instance. In that case we are using the expenseReports data set.
       
    • You can filter the data set rows by adding filters in the Filters section.
       
    • Select the categories property for the Line chart, in this case, the office data property.
       
    • Add the series for the Line chart: the property and the function to apply. In this example, we are using the sum function to calculate the amount per office.
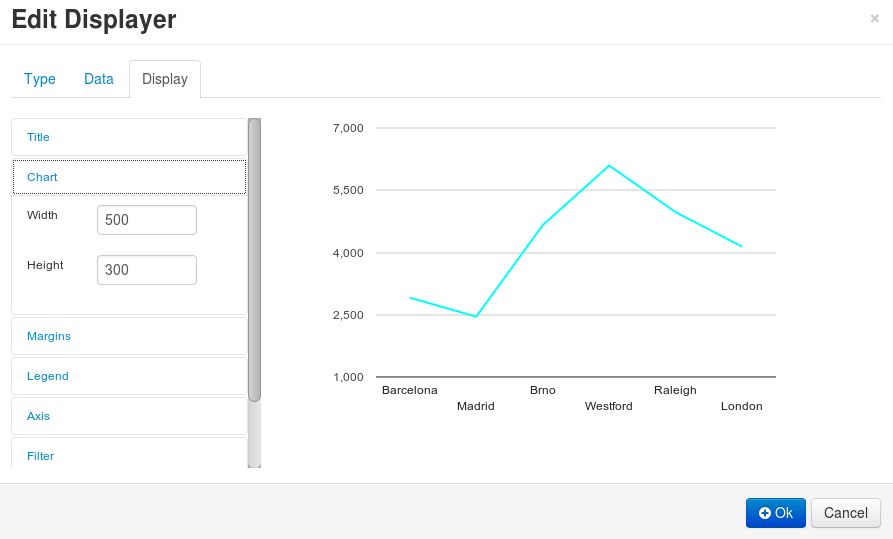
  • Click on Display tab to configure the display settings.


Data Displayer Editor - Display tab

In this tab you have all the displayer settings available for the displayer type selected. Here you can configure the chart position, chart size, chart title, axis titles, margins, legend, tooltips and much more.

Another interesting setting is the renderer selector. It allows to change the RendererLibrary for type of chart. For example, we can switch from GWT to Lienzo charts by just changing the selector value:

Renderer selector
Note that this selector only appears when there exist more than one renderer for the selected displayer type.

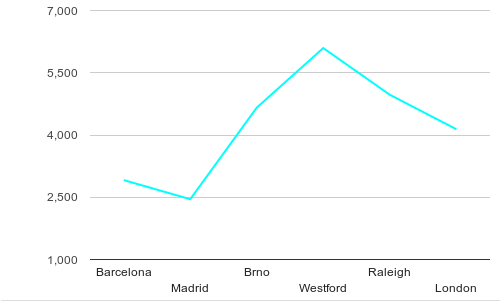
  • Once the type, the data lookup and display settings are configured, just click the OK button to see the results. The chart is rendered according the set of settings defined:


Displayer built using Data Displayer Editor in the UI


    Creating a chart using the Displayer API

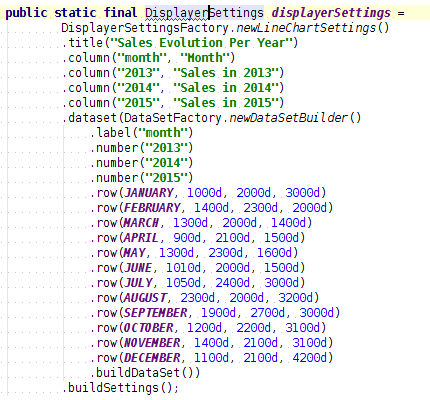
    You can also use the Dashbuilder's API to create a Displayer instance. Basically, the first step is to create a DisplayerSettings instance and use this instance to lookup a Displayer instance that will show the data visualization component. Next screenshot is an example of a DisplayerSettings used to build a Line chart with a data set that contains the sales evolution per year:


    DisplayerSettings creating using Dashbuilder's API

    From the code above:

    1. Use of DisplayerSettingsFactory to create a DisplayerSettings instance for a displayer type, in this example, a line chart.
        
    2. Configure the Displayer configuration parameters such as title, columns, filters and so on. Several API methods are available in the DisplayerSettings interface: title, columns, filters, renderer, sort operations, grouping, etc.
       
    3. Configure a DataSetLookup.
       
      1. You can create a new data set inline as in the example by using the DataSetFactory component.
         
      2. You can use an existing data set by specifying its UUID (the data set must have been previously deployed or created using the UI).
         
    4. Last step is to call the buildSettings method from DisplayerSettingsFactory. It provides the DisplayerSettings instance for your settings. 
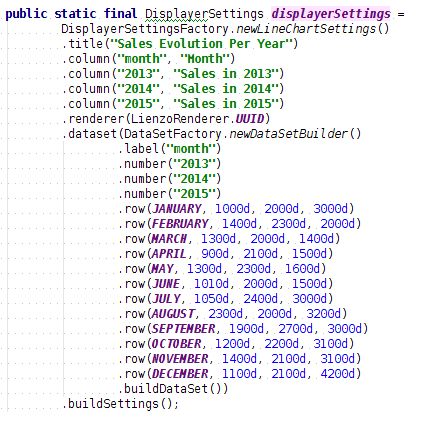
    If you want to use a concrete RendererLibrary for rendering the displayer, you can use the renderer method from DisplayerSettings as:

    Using a concrete renderer via API
                       
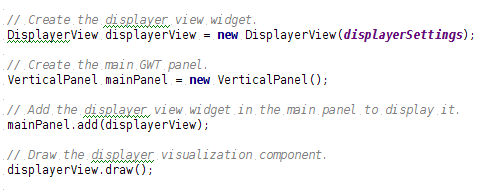
    Once you have the DisplayerSettings instance built you can use the DisplayerHelper class to visualize your displayer in your view page. As easy as follows:
    Creating your view
      As you can see, the constructor for the DisplayerView helper class requires the DisplayerSettings instance previously built and it can be added in any GWT panel, as it's considered a composite GWT widget.

    Once DisplayerHelper widget instance is created and added into your view panels, you can use the draw method to display it. 

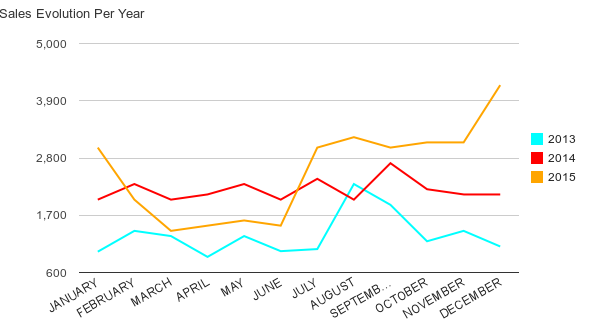
    Finally your view look like:
    Displayer created using Dashbuilder's API
    and.... that's all! :-). For those interested in the API details, please take a look at the Dashbuilder gallery which contains more examples of how to build displayer instances using the API - Gallery examples.

    Friday, February 13, 2015

    UF Dashbuilder and the new data set architecture

       Uberfire and the GWT echosystem brings not only a lot of exciting cool features but also an extremely powerful development environment. UF Dashbuilder stands for the Uberfire-zed version of Dashbuilder.  Since last year, we've been working on rewriting the whole Dashbuilder application on top of Uberfire and GWT. During this migration stage we have rewritten, almost entirely, the backend layer and some of the UI components. There is still a lot of work to do, as we know, but we want to start sharing what we have achieved so far.  In previous articles we showed how to use the technology to build dashboards using the Displayer API. Today we're going to explore the Data Set architecture, how to define and deploy data sets in Dashbuilder and make the dashboards feed from them.

       So what is a data set? Well, basically, it is a set of columns populated with some rows. Another valid definition is: a matrix of data composed by timestamps, texts and numbers values. A data set can be stored into different systems: a database, an excel file, in the memory of an app. or into a lot of other different systems. The good news is that in Dashbuilder there exist an standard way to define a data set, regardless where the data set is stored.

    Data set definitions


      Every time we want to provide access to a given external data, a data set definition has to be deployed. That definition contains information about:
    • where the data set is stored, 
    • how can be accessed, read and/or parsed, and
    • what columns contains and of which type.

        Let's take for instance the following data set definition:

    CSV data set definition example
    CSV data set definition example

         The definition is a JSON document containing the following properties:
    • uuid: A unique universal identifier. 
    • provider: The method used to get access to the data set. Depending on the selected method a set of extra properties need to be provided, For instance, the filePath is needed in CSV along with separatorChar, quoteChar and escapeChar, in order to parse & read the CSV file. 
             At the time of this writing we support the following providers:
      • CSV, for accessing data stored in comma-separated-value files.
      • SQL, for getting data from relational databases through SQL queries.
      • BEAN, a Java bean interface for generating data sets directly from Java. 
      • ELASTICSEARCH, for querying documents stored into Elastic Search indexes.
    • isPublic: if set to true means that it can be accessed from the UI editors by anyone with the right permissions. 
    • columns: this section is used to define which are the data columns we want to be part of the data set, including their type and format.  Columns not defined here will be considered as non-existing  even if they are part of the data stored. There exist 4 types available:
      • date: for date-time values.
      • number: for numeric values.
      • label: for text context that can be categorized.
      • text: for non-categorizable text content (more info at the Data set lookups section).
    • pushEnabled
    • pushMaxSize
    • refreshTime
    • refreshAlways: this 4 properties are related to the caching & refresh mechanisms. Will talk about that later on in the Caching & Refresh section.
        All the properties listed above are common to all the providers, regardless of its type. Let's take a look at some other data set definition examples:

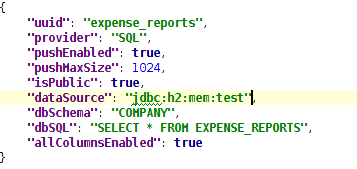
    SQL data set definition   
       For SQL data sets you need to specify an existing app. server dataSource, the dbSchema (optional)  and the dbSQL used to get the data. As you can see the allColumnsEnabled is specific and tells the provider that we want to consider all the columns in the SQL as part of the data set. As for the column types they will be inferred from the database metadata. If we want to override an existing column definition we can still define a columns section as in the CSV example.

    Java Bean generated data set definition

       The Java Bean provider is an extension mechanism that allows to delegate into a Java class the data set generation. In this case we only have to specify a fully qualified class name plus an optional set of parameters that will be passed to the Java Bean.

    Elastic Search data set definition
       The Elastic Search provider is a very good example of integration with a nonSQL storage. The columns serverURL, clusterName, index and type are specific and tells the provider what concrete Elastic Search index and document type this data set defines.


    Data set deployment


      As we've seen so far, Dashbuilder supports several data set types, and it offers a common mechanism for defining such data sets. Once a data set is defined it needs to be deployed, otherwise it won't be accessible to the Dashbuilder modules.

       Dashbuilder is delivered as a web application archive (WAR file). Inside this WAR file there exists a directory called dashbuilder.war/WEB-INF/datasets  containing all the data set definitions. Deploying a new data set it's as easy as creating a .dset file containing our JSON definition and copying that file to the deployment directory. Once detected, the data set definition will be loaded and registered automatically in the Dashbuilder data set registry. Changes made to the deployed files will be also detected. When this happens, the entire data set definition is reloaded and any cached data is removed (see the Refresh & cache section below).

       The following video, shows a live demo of how to deploy a data set at runtime and how the dashboards can get access to it automatically.


       The process described is more intended for technical people. In the next few weeks though, we will be working on a new feature for allowing the end users to edit & deploy its data sets from the UI, the Data Set Editor. We also plan for storing the data sets definitions into GIT repositories through the Uberfire's VFS service as well, to make it easier to share and move data sets between installations.


    Data set lookups 


       So far so good. The next question is: how the charts in a dashboard get the data they need? Well, once a data set is deployed is ready for receiving lookup requests. For instance:

    • Get the total amount of expenses by department
    • Get the outstanding sales till the end of this year, grouped by office
    • Get the orders received in the last 5 minutes
    • Get the travel expenses by employee, only from the sales department 
    • Get the sales pipeline expected for the next few years 

      As you can see, a data set lookup request is basically a query over an existing data set, but with some constraints. To be more specific, a lookup request is a sequence of data manipulation operations which produce a resulting data set. The set of operations supported are:
    • filter: to get a subset of the whole data set by means of specifying constraints on one or multiple data set columns.
    • group: to categorize the whole data sets into groups. LABEL and DATE are the only supported column types. 
    • sort: to sort the resulting data set by one or multiple columns.
    • trim: To limit the maximum number of rows the resulting data set must have.

      A lookup request takes an input data set and produces a resulting data set. As illustrated in the following diagram:

    Data set lookup request
     
      So the way to express some of the examples above as a lookup request is as follows: 
    • Get the total amount of expenses by department
            .dataset("expenses")
            .group("department")
            .column("department")
            .column("amount", "sum")
    • Get the outstanding sales till the end of this year, grouped by office
            .dataset("expenses")
            .filter("date", timeFrame("now till end[year]"))
            .group("office")
            .column("office")
            .column("expectedAmount", "sum")
    • Get the travel expenses by employee, only from the sales department 
            .dataset("expenses")
            .filter("department", equalsTo("sales"))
            .group("employee")
            .column("employee")
            .column("amount", "sum")

         How this lookup requests relates to the displayers/charts in the UI? The answer is that every displayer, no matter whether is a chart, a table or a selector, performs a lookup request in order to retrieve the data required. Obviously, the set of operations in the lookup request varies depending on the chart type. For instance, a pie chart feeds from a two column data set where the first column is usually the result of a group operation, whereas a table displayer can feed both from grouped and non-grouped data sets and they also permits a variable number of columns in the resulting data set.

        For those interested in the internals or just want to see how the Dataset API looks like, I recommend taking a look at the different test cases existing on GitHub.

         Using the Displayer Editor users can configure all the data retrieval settings, as shown in the next screenshot.

      Displayer Editor UI


         From this editor, users can define the lookup's filter, group, and sort operations as well as configuring the resulting data set columns. The editor is adaptable, than means that the available settings varies depending on the displayer type selected. Actually, what the application is doing behind the scenes is building and executing a single lookup request over the selected data set.

      Data providers


          So far, we have learned how to define, deploy and perform data lookup requests on a given data set. Now we're going to go a little deeper in order to describe how the Dashbuilder core deals with the processing of data set lookup requests.

        As we described before, every data set definition is linked to a provider: CSV, SQL, BEAN or ELASTICSEARCH. Each data set lookup  request is delegated to the proper data provider implementation which is responsible for resolving the request. In case of an SQL dataset, the lookup request is transformed into an SQL query which contains all the lookup's filter, group and sort operations.  Thanks to the existing provider interface, Dashbuilder does not have to take care about the lookup request resolution. We can start with a CSV data set definition and move our data to a relational database later on and all our implementations on top of such data set won't break, this includes the dashboards we build and any other client implementations we might have.

        The next diagram shows the internal pieces of the Dashbuilder's Data Set Subsystem. Every lookup request received is processed following these steps:

      1. Get the data set definition the lookup request is referring to.
      2. Get the provider implementation the data set is linked to.
      3. Delegate into the provider the processing of the lookup request. 

      Data Set Subsystem Architecture


         In the diagram, we can see the DataSetDeployer component which looks for data set deployments & updates.  There also exists an especial type of provider called  StaticProvider which holds and resolves lookup requests in memory. Unlike the SQL or ELS providers which execute queries against the external data storage, the CSV and BEAN providers are not query processing engines. So what they actually do is to read/generate and register the whole data set into the static (in-memory) provider. This is specially helpful for small data set use cases. For big data scenarios you should definitely consider using an SQL or ELS provider.  

         When the first lookup request over a CSV data set is requested, the CSVProvider loads, registers and delegates into the StaticProvider the lookup request processing.  So the CSV and BEAN providers are just data set loaders since the real processing is carried out by the static provider. The static provider relies on a data set operation engine implementation capable of resolving a sequence of filter, group and sort operations over a data set (further details in the next section).


      Caching & Refresh


         In the beginning of this article we stated that a data set definition may contain four extra properties:

      • pushEnabled (false by default )
      • pushMaxSize (1024Kb by default )
      • refreshTime (-1=disabled by default)
      • refreshAlways (false by default )

      All of them are related with the caching & refresh mechanisms. Let's take a look at the following diagram which depicts the Dashbuilder's client/server architecture.   


      Client/Server Architecture 

         Imagine we have an end user interacting with a dashboard. Let's see what happens when a chart issues a data set lookup request:

         1. The DataSetClientServices class receives the request  and 
         2. ... asks the server for the data set metadata which contains the data set definition, size, ... 

         If  "pushEnabled=true" and "pushMaxSize<dataSetSize" then,

         3. The whole data set is pushed to the browser. 
         4. The data set is registered into the ClientDataSetManager.
         5. Finally, the initial (and the subsequent) data set lookup request is processed on the client.

         If  "pushEnabled=false" or "pushMaxSize is not < dataSetSize" then the lookup requests is always processed in the backend. 

         The push mechanism allows for uploading an entire data set to the user's browser. It applies to any kind of data set, no matter what is the provider type. It's a kind of browser caching mechanism. The main motivations behind this mechanism are the following:

      • Improve the performance. Once a data set is loaded all the data set group, filter sort operations performed issued from the UI are resolved without any further calls to the backend.
      • Support a pure lightweight client approach. The whole Dashbuilder UI components could be used without the need of the backend layer. Data sets can be registered through calls to the  ClientDataSetManager and all the lookup requests will be resolved at a client side. Obviously, this approach is not suitable for large data sets.


         The DataSetManager interface is the main entry point for any data set access operation, including the lookup requests. As shown in the diagram, there exists two implementations of the DataSetManager interface, one in GWT and  a server implementation in pure Java.  Both depend on the DataSetOpEngine, which is a GWT shared implementation that can run on both client & server, this makes possible the ability to process lookup requests in the client side.


         So far, so good. However, what if a data set is pushed and the source data is updated? or, for instance, what if a CSV file changes or if a new document is added to an Elastic Search index? Here is when the two remain settings refreshTime & refreshAlways  comes into action.


         Imagine a database which is updated every night. If we want to get the most updated data then we must set "refreshTime=1day" and "refreshAlways=true". On the contrary, if our data changes every now and then then we must set "refreshAlways=false" which means that the system will ask the database (once a day) whether the data set is outdated before invalidating the current data set.

         For SQL/ELS data sets , it makes no sense to set the refresh settings if push is disabled, since all the lookup requests will always be executed against the external storage.  Otherwise, for CSV/BEAN it always makes sense, since the contents of the data sets are always loaded and cached in the backend.

        For every data set with refresh enabled, an invalidation task is registered into the Scheduler component, as shown in the diagram above. When the refresh interval is reached, the task is executed,  a DataSetStaleEvent is fired and any data set cached data (both on the client & backend) is removed.

         From the UI perspective we can control in detail when we want a chart to get refreshed. The refresh settings are located in the Displayer Editor > Display tab > Refresh category. One option is to refresh every time a DataSetStaleEvent is received. Another option is to force to refresh every N seconds. This last option is  more suitable for real-time use cases.
       
         To sum up, if we know our data is going to change and if we want our dashboards to be notified on every update we must enable the refresh settings. Optionally, if we want to improve our dashboard performance then we can go for enabling the data push feature, but only if our data set is small enough.

         In next articles we will talk about real-time dashboards, how to build them and how to integrate Dashbuilder with a non SQL storage like Elastic Search. Stay tuned!